Abhibhaw Asthana

Work / Devtron · AI infrastructure

GPU Platform: GPUs without tickets

AI teams waited days for a GPU and weeks to ship a model. I defined a self-service GPU platform where infra teams set the rules once and AI teams move on their own.

was days now self-serveto get a GPU
80%+fewer GPU tickets
23%better GPU utilization and allocation, on average
User
Enterprise AI teams that train and serve models, and the infra teams that run their GPU clusters.
Problem
Every GPU went through an infra ticket. Teams waited days to get one and weeks to ship a model. Costly GPUs sat idle or stayed locked to one team.
Decision
Self-service GPU workspaces, training jobs and one-click model deploys. Infra teams set quotas, usage policies and GPU sharing once, and the platform enforces them.
Not built
A custom GPU scheduler. The platform builds on proven open-source schedulers (Kubeflow and Kueue), and the work went into self-service and policy. Multi-cluster support came later.
Result
GPU tickets fell by 80%+. Developers got full self-service. GPU utilization and allocation improved by 23% on average.

How it works

Teams waited too long, and the GPUs were used too little. Both came from one team doing every step by hand.

Before
  1. AI engineer
  2. opens a ticket
  3. removed: Infra teamchecks capacity by hand, days
  4. sets it up
  5. GPUkept by one team, often idle
After
  1. Infra teamsets quotas, policies, sharing once
  2. rules apply to every request
  3. Platform
  4. AI engineer self-serves
  5. GPUnotebook, training job or model deploy
The ticket left the path. Infra teams set the rules once, before any request.
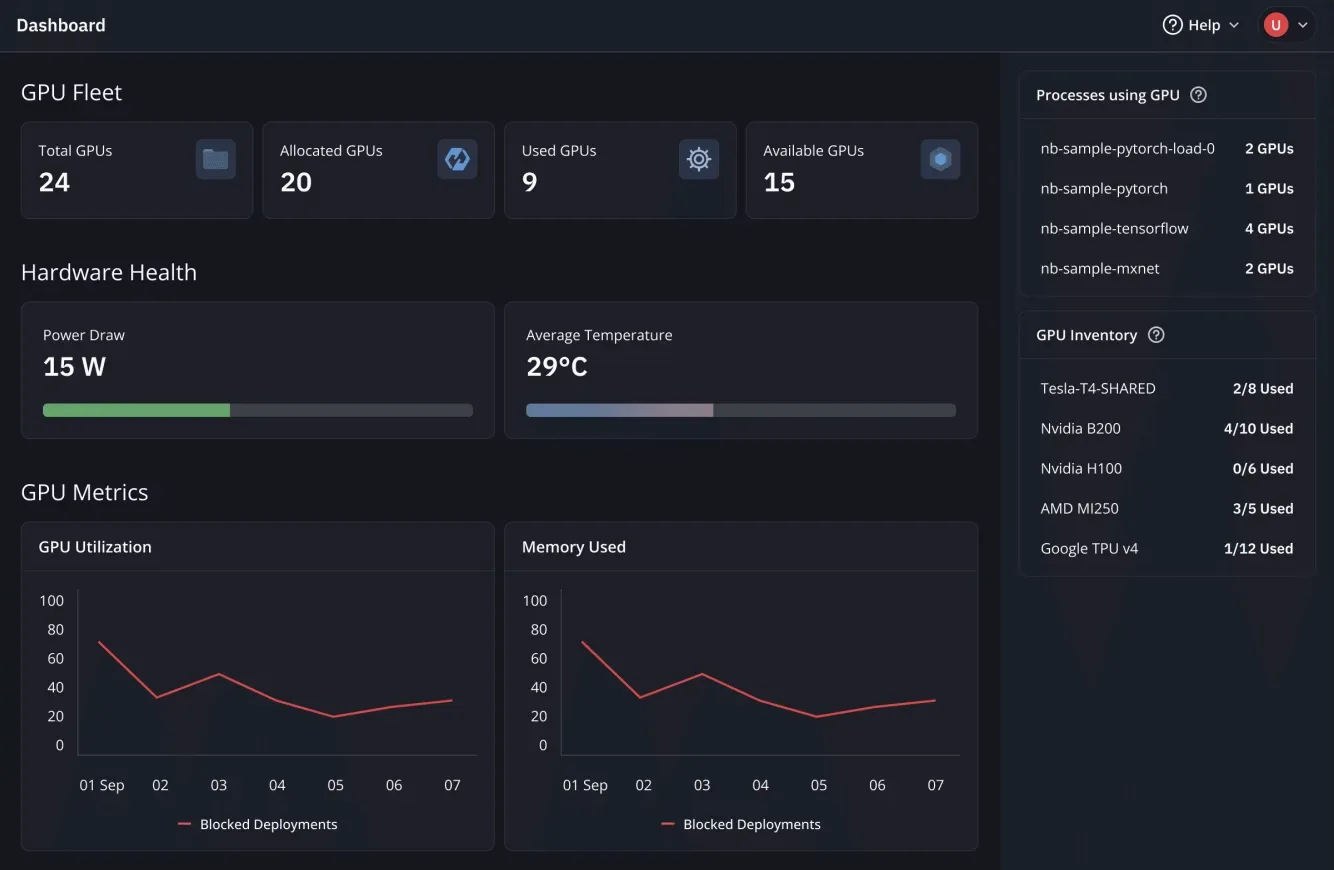
GPU fleet dashboard showing total, allocated, used and available GPUs, utilization charts and a GPU inventory by type

The fleet view turns a capacity argument into a number. Public product image from devtron.ai, with sample data.

What I left out

A new GPU scheduler. Open-source schedulers already place work well, so the effort went where teams waited: access, policy and deployment.
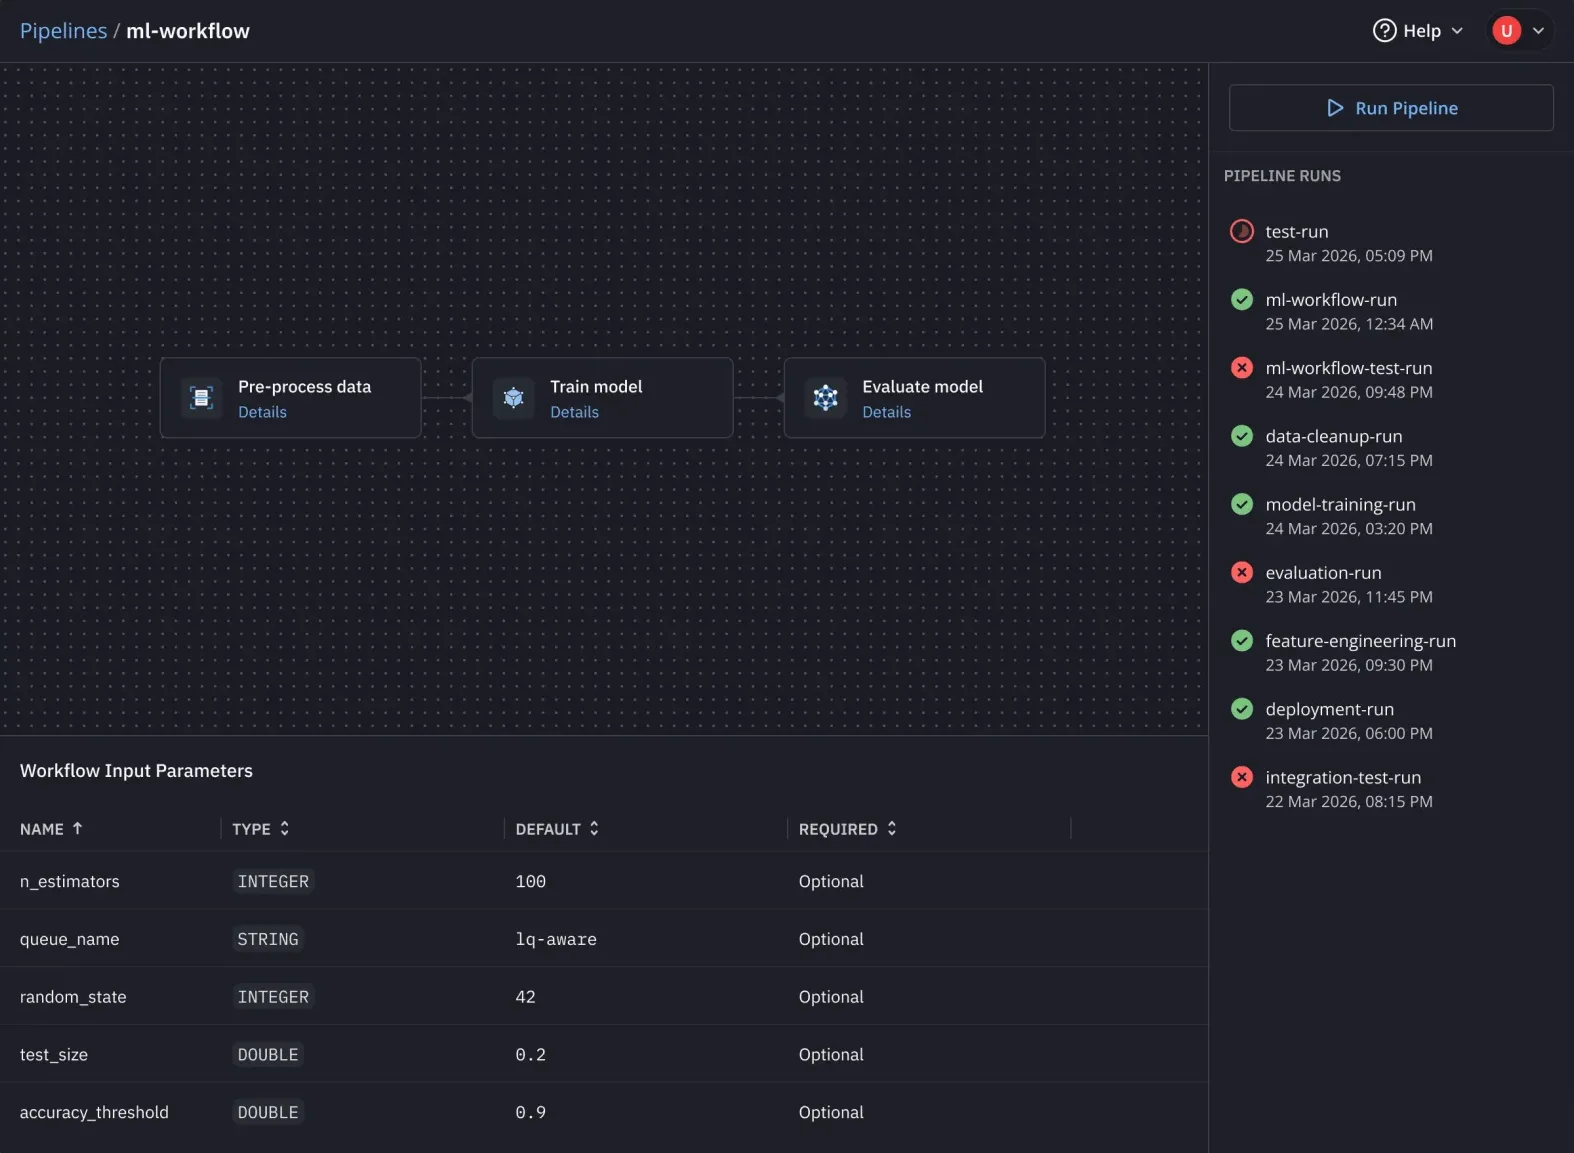
ML pipeline graph with pre-process, train and evaluate steps, run history and input parameters

Training pipelines run from the same interface. Public product image from devtron.ai, with sample data.

What happened

  • GPU tickets fell by more than 80%.
  • Developers got full self-service for notebooks, training and model deploys.
  • GPU utilization and allocation improved by 23% on average.