How it works
Kubernetes says that something failed. It rarely says why.
Before
- Deploy fails
- user digs
removed: Events, logs, configsread by hand, hours- or gives up
- Support ticket
After
- Deploy fails
- user clicks Explain
- Atlasreads events, logs and service context
- about a minute
- Cause and fixa person decides
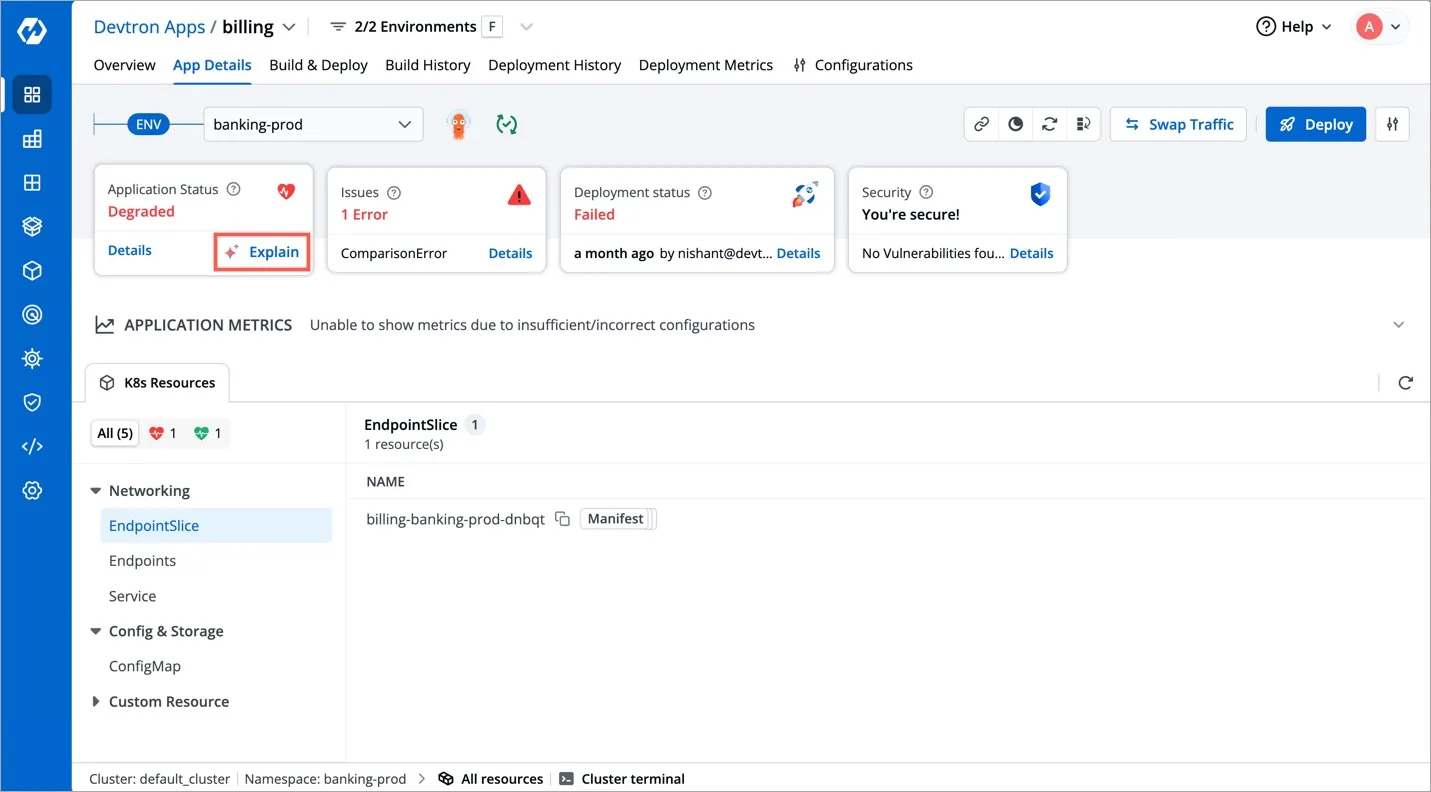
The entry point is the failure itself. Public image from Devtron docs.
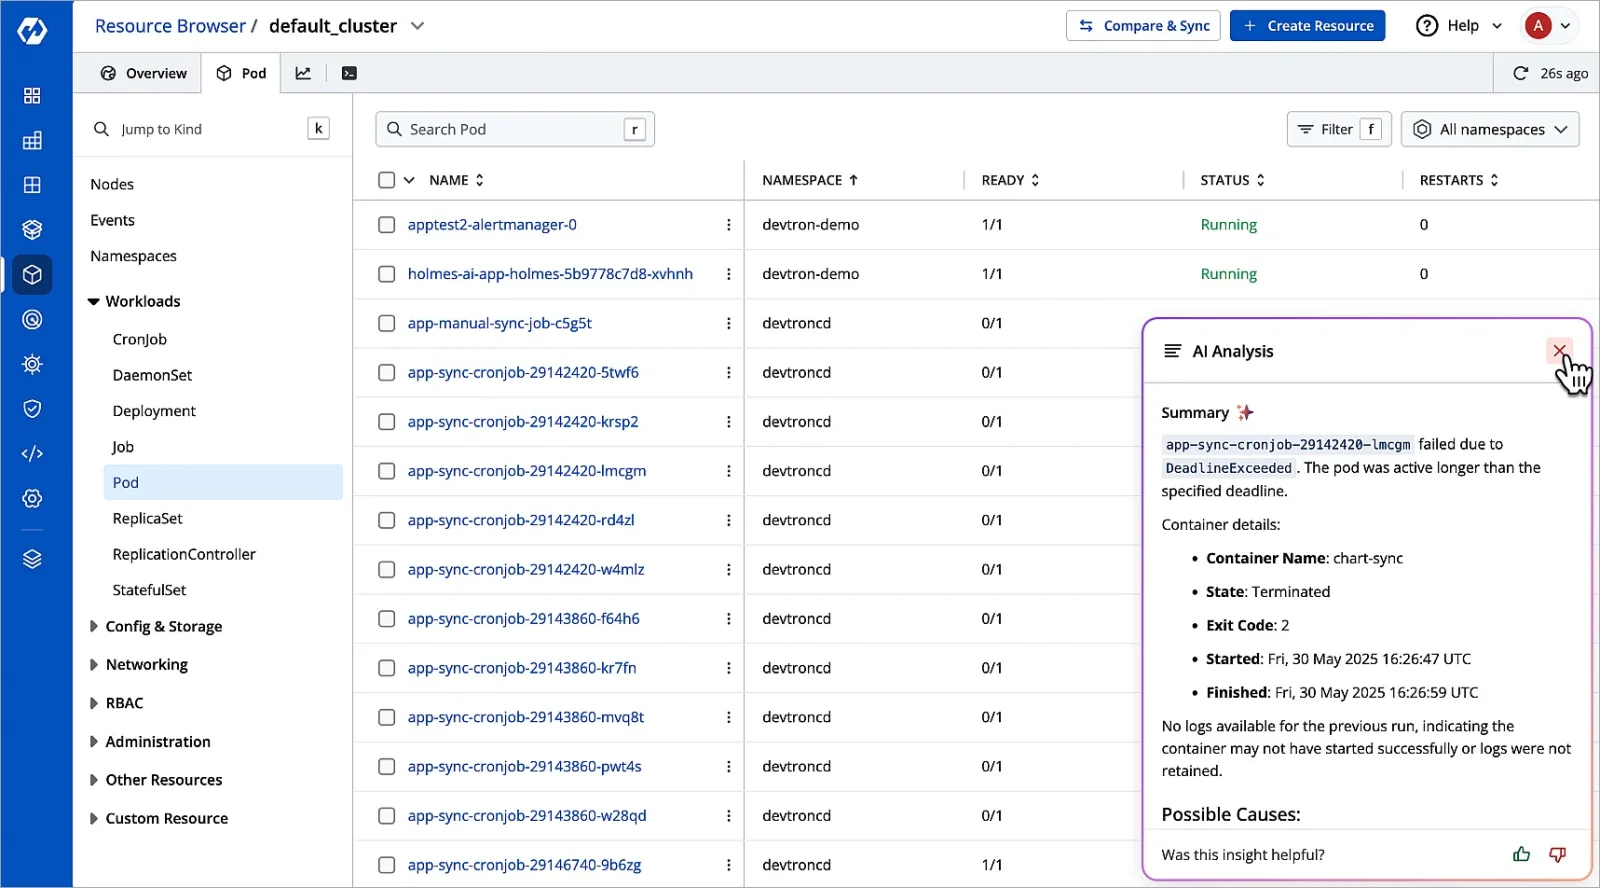
The answer names the cause and likely fixes. Users rate each answer. Public image from Devtron docs.
What I left out
- Automatic fixes. Version one explained and suggested. Approved runbooks with an audit log came later.
- A model of our own. Teams bring the LLM provider they already approved.
What happened
- Root-cause time fell from hours to about a minute.
- Recovery time fell from hours to minutes.